VICHEL GLOBAL / CORPORATE
Trusted AI compute infrastructure for a multilingual world
Vichel Global operates distributed AI compute sites across multiple regions and unifies them through a single software platform. We serve institutions with strict requirements for data residency, performance and availability, with auditable and sustainable compute services.
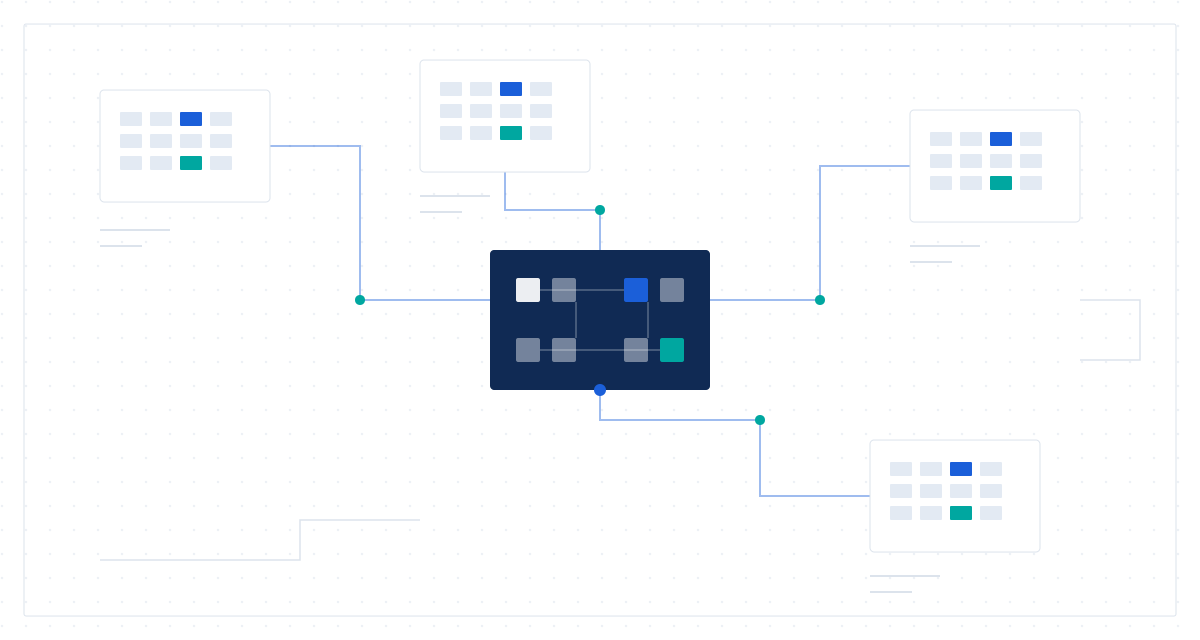
Four regions
Distributed sites coordinated by one control plane.
Multilingual inference
Optimised for CJK and Arabic workloads.
Hardware isolation
Tenant separation enforced below the hypervisor.
One platform
Scheduling, networking, storage and isolation under one governance model.
01 / WHAT WE DO
Infrastructure delivered as a service
We start with the physical layer. Power, facilities, networking, scheduling and inference software are integrated into one deliverable service. Instead of coordinating multiple vendors, customers use a single interface and an agreed service level, with data boundaries and responsibilities set out in the contract.
02 / OUR APPROACH
A system that is calibrated over time
We treat infrastructure as a long-term system rather than a one-off purchase. Workloads are matched to the sites best suited to their latency, residency and energy profile, and software efficiency is improved through quantisation, caching and scheduling rather than hardware accumulation alone.
03 / TECHNOLOGY
One governance model for every workload
SovereignOS, our unified compute platform, covers isolation, networking, scheduling and storage. Highly sensitive workloads and elastic workloads run under the same governance framework, with customer-managed keys and auditable access controls.
Explore Technology04 / TRUST
Compliance as a design constraint
Data residency, export control discipline, recognised assurance benchmarks and responsible operations form the basis of every engagement. Current status is always defined in formal documentation and contract terms rather than on this website.
Read about TrustINFRASTRUCTURE
A network of four regional sites
Each site carries a distinct role — control plane, low-latency inference, regional dedicated capacity and offline batch processing — rather than replicating the same configuration everywhere.
Korea
Control plane and core research
Malaysia
Low-latency regional inference
United Arab Emirates
Regional dedicated capacity
Kazakhstan
Offline batch and compute-intensive work
SOLUTIONS
Ways to work with us
Dedicated Clusters
Long-term reserved capacity with defined isolation boundaries.
02Capacity Partnership
Structured collaboration on planned compute capacity.
03Elastic GPU
On-demand compute for variable workloads.
04Multilingual MaaS API
Model serving with language-aware inference optimisation.
05Managed Operations
Operational support across the full service lifecycle.
TRUST & COMPLIANCE
Compliance as a design constraint
Current status is always defined in formal documentation and contract terms.
Read about TrustStart a technical conversation
If your organisation is evaluating compute deployment, data residency or inference performance, we would be glad to discuss your requirements.